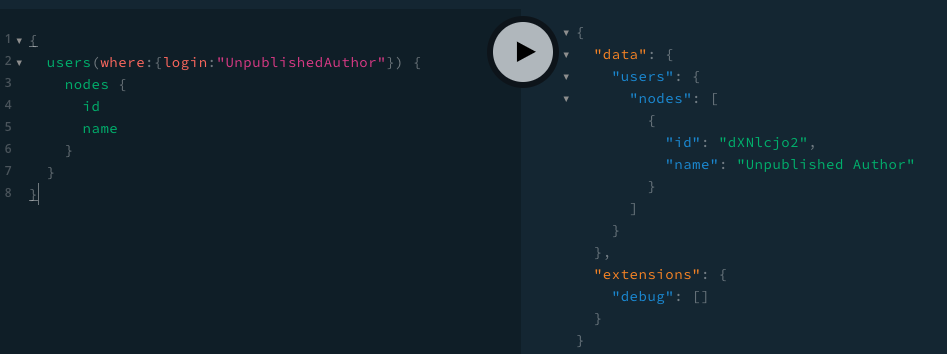
The goal of this article is to make a non-authenticated GraphQL query for a User with no published content and to get the User returned in the response.
Like the following:
{
  users(where:{login:"UnpublishedAuthor"}) {
    nodes {
      id
      name
    }
  }
}
NOTE: To test these queries you will want to use a GraphQL client that is not Authenticated, such as GraphQL Playground or Altair. WPGraphiQL, the GraphiQL IDE built-in to WPGraphQL in the WordPress dashboard currently executes GraphQL queries as your authenticated user.
The Problem
WPGraphQL respects WordPress core access control rights. Meaning that data which is exposed publicly by WordPress core is exposed publicly in WPGraphQL, but data that is exposed only in the WordPress Dashboard is restricted by WPGraphQL to GraphQL requests made by authenticated users with proper capabilities to see the data.
In WordPress, users that have not published content are not public entities and WPGraphQL respects this.
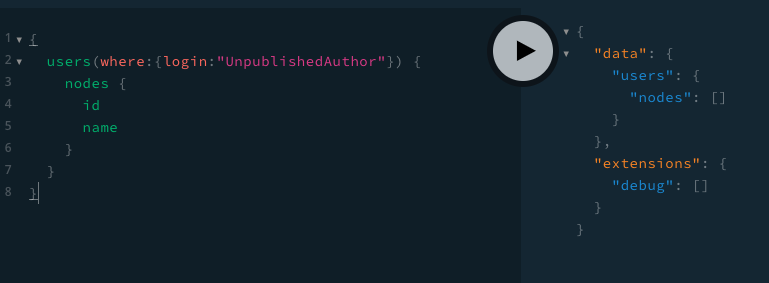
This means by default, the same query as above would return empty results, because the “UnpublishedAuthor” user is not allowed to be seen by a public, non-authenticated GraphQL request.
In some cases, you might decide you want to show Users that don’t have published content in the results of your WPGraphQL Queries.
The Solution
The below snippets should help accomplish this.
Adjust the underlying WP_User_Query
When using WPGraphQL to query a connection (a list) of users, WPGraphQL sets an argument of 'has_published_posts' => true for the underlying WP_User_Query, meaning that the SQL query for a list of users will reduce the results to users that have published posts.
To adjust this, we can use the `graphql_connection_query_args` like so:
WPGraphQL has a Model Layer that centralizes the logic to determine if any given object, or fields of the object, should be allowed to be seen by the user requesting data.
The User Model prevents unpublished users from being seen by non-authenticated WPGraphQL requests.
To lift this restriction, we can use the following filter:
add_filter( 'graphql_object_visibility', function( $visibility, $model_name, $data, $owner, $current_user ) {

  // only apply our adjustments to the UserObject Model
  if ( 'UserObject' === $model_name ) {
    $visibility = 'public';
  }

  return $visibility;

}, 10, 5 );
Testing our Changes
Now that we’ve adjusted WPGraphQL to show all users to public GraphQL requests, we can use GraphiQL to test.
For the sake of testing, I created a new User with the name of “Unpublished Author” and will make a GraphQL Query for users, like so:
{
  users {
    nodes {
      id
      name
    }
  }
}
And with the above snippets in place, I’m now able to see the UnpublishedAuthor in my GraphQL query results.
If you manage custom fields in WordPress using Advanced Custom Fields, and you want to use WPGraphQL to get a list of posts filtering by the ACF field value, you’ll need to implement a few things in your themes functions.php.
Summary:
Register a new “where” argument to the WPGraphQL Posts connection
Filter the Posts connection resolver to account for this new argument
Register the new “where” argument:
First you need to create a add_action on graphql_register_types that will look something like the following code snippet. Here we register a field on the RootQueryToMyCustomPostTypeConnectionWhereArgs where you can define MyCustomPostType as your post type. The type we register will be an ID (This can also be of type Boolean, Float, Integer, orString) for my case I wanted to get only posts that where connected to an other post via the ACF post object field (the field was set to return only the Post ID).
Filter the connection resolver
add_action('graphql_register_types', function () {

    $customposttype_graphql_single_name = "MyCustomPostType";

    register_graphql_field('RootQueryTo' . $customposttype_graphql_single_name . 'ConnectionWhereArgs', 'postObjectId', [
        'type' => 'Int',
        'description' => __('The databaseId of the post object to filter by', 'your-textdomain'),
    ]);
});
Next we have to create an add_filter to graphql_post_object_connection_query_args. If you are familiar with WordPress loops via WP_Query, here we set the $query_args like we would do on any other loop, but we check for your custom where:.
The key will be the name of the field, the value will be the value you will give the postObjectId: "123" in your query, speaking of the query that will ook something like
WPGraphQL makes use of cursor-based pagination, inspired by the Relay specification for GraphQL Connections. If you’re not familiar with cursor-based pagination it can be confusing to understand and implement in your applications.
In this post, we’ll compare cursor-based pagination to page-based pagination, and will look at how to implement forward and backward pagination in a React application using Apollo Client.
Before we dive into cursor-based pagination, let’s first look at one of the most common pagination techniques: Page-based pagination.
Page Based Pagination
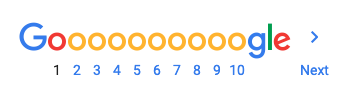
Many applications you are likely familiar with paginate data using pages. For example, if you visit Google on your desktop and search for something and scroll down to the bottom of the page, you will see page numbers allowing you to paginate through the data.
Screenshot of Google’s pagination UI
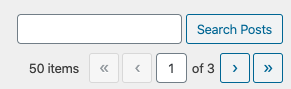
WordPress also has page-based pagination mechanisms built-in. For example, within the WordPress dashboard your Posts are paginated:
Screenshot of the WordPress dashboard pagination UI
And many WordPress themes, such as the default TwentyTwenty theme feature page-based pagination:
Screenshot of the TwentyTwenty theme pagination UI
How Page-Based Pagination Works
Page-based pagination works by calculating the total number of records matching a query and dividing the total by the number of results requested for each page. Requesting a specific page results in a database request that skips the number of records totaling the number of records per page multiplied by the number of pages to skip. For example, visiting page 9 on a site showing 10 records per page would ask the database to skip 90 records, and show records 91-100.
Performance Problems with Page-Based Pagination
If you’ve ever worked with on a WordPress site with a lot of records, you’ve likely run into performance issues and looked into how to make WordPress more performant. One of the first recommendations you’re likely to come across, is to not ask WordPress to calculate the total number of records. For example, the 10up Engineering Best Practices first recommendation is to set the WP_Query argument no_found_rows to true, which asks WordPress to not calculate the total records.
As the total number of records grow, the longer it takes for your database to execute this calculation. As you continue to publish posts, your site will continue to get slower.
In addition to calculating the total records, paginated requests also ask the database to skip a certain number of records, which also adds to the weight of the query. In our example above, visiting page 9 would ask the database to skip 90 records. In order for a database to skip these records, it has to first find them, which adds to the overall execution. If you were to ask for page 500, on a site paginated by 100 items per page, you would be asking the database to skip 50,000 records. This can take a while to execute. And while your everyday user might not want to visit page 500, some will. And search engines and crawlers will as well, and that can take a toll on your servers.
The (lack of) Value of Page Numbers in User Interfaces
As a user, what value do page numbers provide in terms of user experience?
For real. Think about it.
If you are on my blog, what does “page 5” mean to you?
What does “page 5” mean to you on a Google search results?
Sure, it means you will get items “50-60”, but what does that actually mean to you as a user?
You have no realistic expectation for what will be on that page. Page 5 on my blog might be posts from last week, if I blogged regularly, but Page 5 also might be blog posts from 2004. You, as the user don’t know what to expect when you click a page number. You’re just playing a guessing game.
It’s likely that if you clicked page 5 on my blog, you are looking for older content. Instead of playing a guessing game clicking arbitrary page numbers, it would make more sense and provide more value to the user if the UI provided a way to filter by date ranges. This way, if you’re looking for posts from yesterday, or from 2004, you could target that specifically, instead of arbitrarily clicking page numbers and hoping you find something relevant to what you’re looking for.
Inconsistent data in page-based UIs
Page based UIs aren’t consistent in the content they provide.
For example, if I have 20 blog posts, separated in 2 pages, page 1 would include posts 20-11 (most recently published posts), and page 2 would include posts 1-10. As soon as I publish another article, page 1 now would include items 21-12, page 2 would include items 2-11, and we’d have a page 3 with item 1, the oldest post.
Each time a new blog post is published, the content of each paginated archive page changes. What was on page 5 today, won’t be the same next time content is published.
This further promotes the fact that the value provided to users in page numbers is confusing. If the content on the pages remained constant, at least the user could find the content they were looking for by always visiting page 5, but that’s not the case. Page 5 might look completely different next time you click on it.
Cursor-Based Pagination
Many modern applications you’re likely familiar with use cursor-based pagination. Instead of dividing the total records into chunks and skipping records to paginate, cursor-based pagination loads the initial set of records and provides a cursor, or a reference point, for the next request to use to ask for the next set of records.
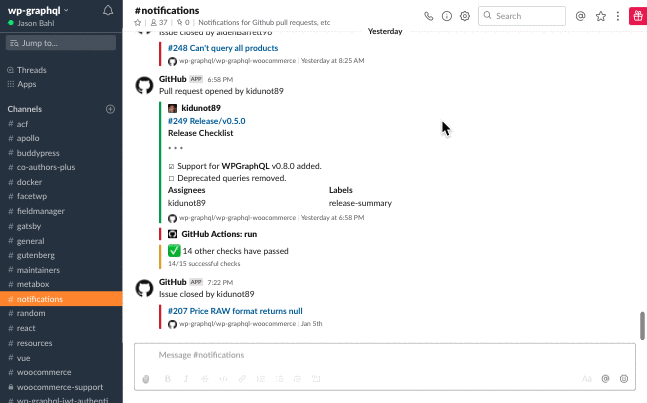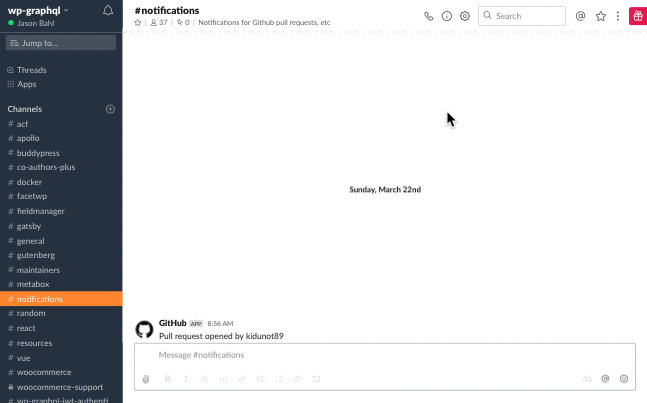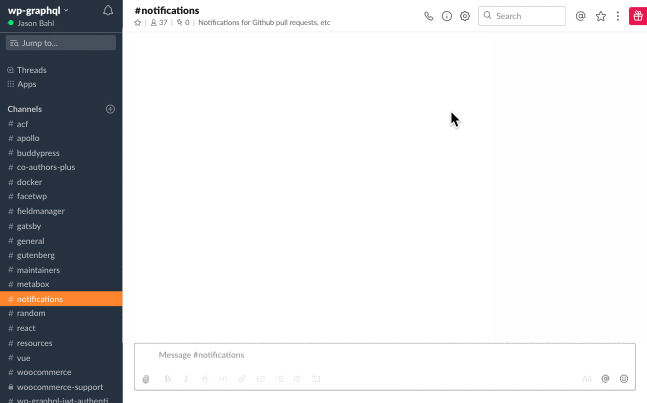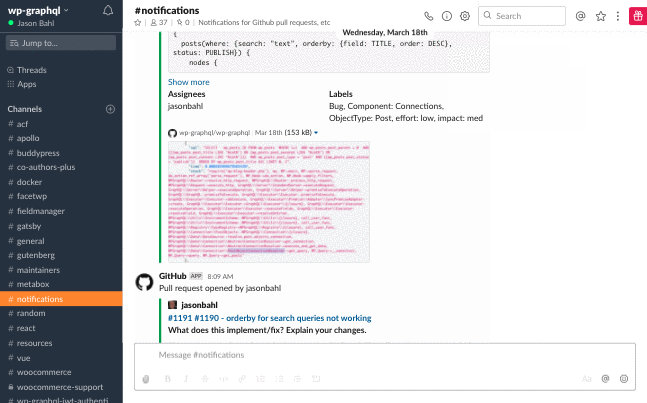
Some examples of this type of pagination in action would be loading more tweets as you scroll on Twitter, loading more posts as you scroll on Facebook, or loading more Slack messages as you scroll in a channel.
Animated GIF demonstrating scrolling in Slack to load more messages
As you scroll up or down within a Slack channel, the next set of messages are loaded into view (often so fast that you don’t even notice). You don’t arbitrarily click page numbers to go backward or forward in the channel and view the next set of messages. When you first enter a channel, Slack loads an initial list of messages and as you scroll, it uses a cursor (a reference point) to ask the server for the next set of messages.
In some cases, such as Slack channels, infinite scrolling for pagination can enhance the user experience. But in some cases, it can harm the user experience. The good news is that cursor-based pagination isn’t limited to being implemented via infinite scroll. You can implement cursor pagination using Next / Previous links, or a “Load More” link.
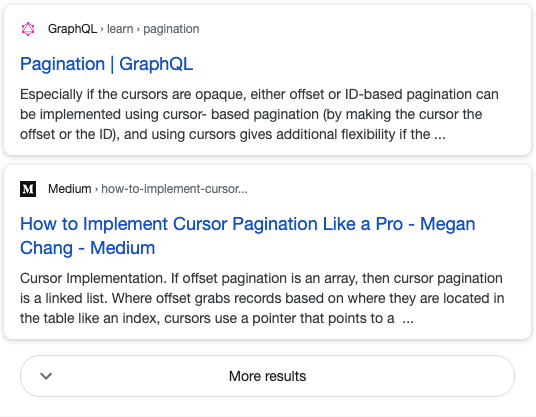
Google, for example, when used on mobile devices uses a “More results” button. This avoids subjecting users to the guessing game that page numbers lead to, and also avoids some of the downsides of infinite scrolling.
Screenshot of Google search results with a “More results” button, as seen on a mobile device
Performance of Cursor Based Pagination
Cursor pagination works by using the reference, the cursor, to point to a specific place in the dataset, and move forward or backward from that point. Page-based pagination needs to skip x amount of records, where cursor pagination can go directly to a point and start there. As you page through records with page-based pagination your queries get slower and slower, and it’s further impacted by the size of the dataset. With cursor pagination, the size of your dataset doesn’t affect performance. You are going to a specific point in the dataset and returning x number of records before or after that point. Going 500 pages deep will get quite slow on page-based, but will remain equally performant with cursor-based pagination.
No Skipped Data
Let’s say you visit your Facebook newsfeed. You immediately see 5 posts from your network of family and friends. Let’s say the data looks something like the following:
COVID-19 update from Tim
Meme from Jen
Embarrassing Photo 1 from Mick
Embarrassing Photo 2 from Mick
Dog photo from Maddie
Quarantine update from Stephanie
Inspirational quote from Dave
Breaking Bad meme from Eric
Quarantine update from your local newspaper
Work from Home tips from Chris
In page-based pagination, the data would look like so:
Page 1
Page 2
COVID-19 update from Tim
Quarantine update from Stephanie
Meme from Jen
Inspirational quote from Dave
Embarrassing Photo 1 from Mick
Breaking Bad meme from Eric
Embarrassing Photo 2 from Mick
Quarantine update from your local newspaper
Dog photo from Maddie
Work from Home tips from Chris
Let’s say Mick wakes up and realizes he shouldn’t have posted the embarrassing pics. He deletes the pics at the same time you’re looking at Page 1 of the posts.
When you scroll to look at more posts, the overall dataset now looks like the following:
Page 1
Page 2
COVID-19 update from Tim
Breaking Bad meme from Eric
Meme from Jen
Quarantine update from your local newspaper
Dog photo from Maddie
Work from Home tips from Chris
Quarantine update from Stephanie
5 Keto Recipes from Barb
Inspirational quote from Dave
“Tiger King” trailer from Cassie
Since the two embarrassing photos were deleted, page 2 now looks different. Both “Quarantine update from Stephanie” and “Inspirational quote from Dave” are not on Page 2 anymore. They slid up to page 1. But the user already loaded page 1 which included the now deleted pice. So, when you scroll, and page 2 loads, these two posts won’t be included in your feed!
With page-based pagination, you would miss out on some content and not have any way to know that you missed it!
And Dave and Stephanie will be sad that you didn’t like their posts.
This happens because the underlying SQL query looks something like this:
SELECT * from wp_posts OFFSET 0, LIMIT 5 // Page 1, first 5 records
SELECT * from wp_posts OFFSET 5, LIMIT 5 // Page 2, skips 5 records regardless
With cursor pagination, a pointer is sent back and used to query the next set of data. In this case, it might be a timestamp. So, when you scroll to load more posts, with cursor pagination you would get all items published after the last cursor. So, “Quarantine update from Stephanie” and “Inspirational quote from Dave” would be included because they were posted after the timestamp of the embarrassing photos that have been deleted. The cursor goes to a specific point in the dataset, and asks for the next set of records after that point.
The underlying SQL query for cursor pagination looks something like this:
SELECT * from wp_posts WHERE cursor > wp_posts.post_date ORDER BY wp_posts.post_date LIMIT 5
So, instead of skipping 5 records, we just get the next set of posts based on publish date (or whatever the query is being ordered by). This ensures that the user is getting the proper data, even if there have been changes to the existing dataset.
Cursor Pagination with WPGraphQL
Below is an example of forward and backward pagination implemented in a React + Apollo application.
(If your browser isn’t loading this example application below, click here to open it in a new window)
In this example, we’ll focus specifically on the list.js file.
Paginated Query
One of the first things you will see is a paginated query.
query GET_PAGINATED_POSTS(
    $first: Int
    $last: Int
    $after: String
    $before: String
  ) {
    posts(first: $first, last: $last, after: $after, before: $before) {
      pageInfo {
        hasNextPage
        hasPreviousPage
        startCursor
        endCursor
      }
      edges {
        cursor
        node {
          id
          postId
          title
        }
      }
    }
  }
In this query, we define the variables first, last, after and before. These are options that can be passed to the query to affect the behavior. For forward pagination first and after are used, and for backward pagination last and before are used.
In addition to asking for a list of posts, we also ask for pageInfo about the query. This is information that informs the client whether there are more records or not, and how to fetch them. If hasNextPage is true, we know we can paginate forward. If hasPreviousPage is true, we know we can paginate backwards.
Our PostList component makes use of the Apollo useQuery hook to make an initial query with the variables: { first: 10, after: null, last: null, before: null }. This will ask WPGraphQL for the first 10 posts, which will be the 10 most recently published posts.
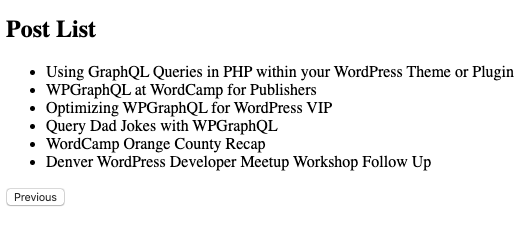
When the data is returned, we map over the posts and return them and render the Post titles as unordered list items.
Next / Previous buttons
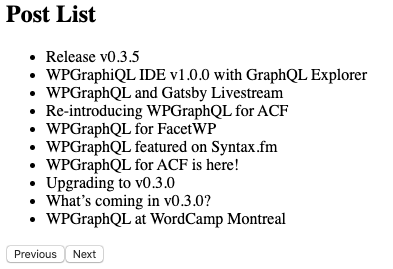
Since there are more than 10 posts, the pageInfo.hasNextPage value will be true, and when this value is true, we know we can safely show our Next button. Since this is the first page of data, there are no posts more recent, so pageInfo.hasPreviousPage will be false. Since this is false, we will not load the Previous Button.
The initial load of the application is a list of 10 posts with a Next button.
Screenshot of the example application’s initial loaded state
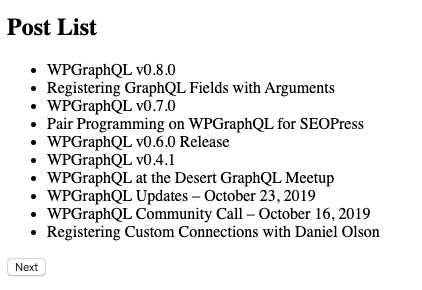
When the “Next” button is clicked, it makes use of the Apollo fetchMore method, and re-queries the same query, but changing the variables to: { first: 10, after: pageInfo.endCursor, last: null, before: null }. These variables tell WPGraphQL we want the first 10 posts after the endCursor, which is a reference to the last item in the list on the first page. When those posts are returned, we make use of Apollo’s updateQuery method to replace the Post list with the new list.
So now, after clicking “Next”, we have a new list of posts displayed, and both a “Previous” and “Next” button.
Screenshot of the example application after clicking the “Next” button
Both the Previous and Next buttons are displayed, because the values for pageInfo.hasNextPage and pageInfo.hasPreviousPage were both true. This information from the query tells the client that there are posts on either side, so we can paginate forward or backward.
If we click “Next” a few more times, we will reach the end of the dataset, and pageInfo.hasNextPage will be false, and we will no longer want to show the “Next” button.
Screenshot of the example application at the end of the dataset
When the “Previous” button is clicked, it makes use of the Apollo fetchMore method, and re-queries the same query, but changing the variables to: { first: null, after: null, last: 10, before: pageInfo.startCursor }. These variables tell WPGraphQL we want the last 10 posts before the startCursor, which is a reference to the first item in the list on the page. This allows us to paginate backward and get the previous items.When those previous posts are returned, we make use of Apollo’s updateQuery method to replace the Post list with the new list, and we’re back to showing both “Previous” and “Next” buttons again, until you click previous enough times to be back at the beginning of the dataset.
Summary
In this post, I compared page-based pagination and cursor-based pagination. We then looked at an example application built with React and Apollo querying the WPGraphQL.com GraphQL API and implementing forward and backward pagination.
I hope this article helps inspire you to use WPGraphQL in fun ways as we build the future of the web together!
One of the most common ways to customize the WPGraphQL Schema is to register new fields.
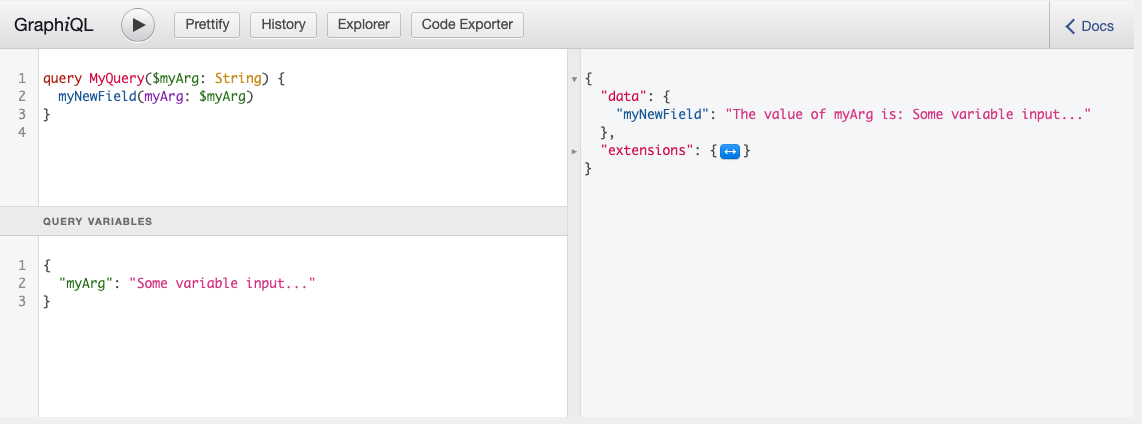
When registering fields, argument(s) can also be defined for the field.
Field arguments in GraphQL allow input to be passed to the field, and when the field is resolved, the input of the field argument can be used to change how the field is resolved.
Registering Fields
Below is an example of registering a field with an argument:
This action hooks into WPGraphQL when the WPGraphQL Schema is being generated. By hooking our code here, it makes sure our function is only executed when WPGraphQL is being used.
Define the Field Config
Within that action, we define a $field_config array which gets passed to the register_graphql_field() function.
$field_config = [
  'type' => 'String',
  'args' => [
    'myArg' => [
      'type' => 'String',
    ],
  ],
  'resolve' => function( $source, $args, $context, $info ) {
    if ( isset( $args['myArg'] ) ) {
      return 'The value of myArg is: ' . $args['myArg'];
    }
    return 'test';
  },
];
Within the field config we define the following:
type: We define the type as “String” to tell WPGraphQL that the field is a String in the Schema
args: We define an array of arguments that will be available to the field.
resolve: We define a function to execute when the field is queried in GraphQL. Resolve functions in GraphQL always receive 4 arguments ($source, $args, $context, $info). The argument we care about for this example is the 2nd one, $args. We check to see if that argument is set, and if it is, we append the value to the string “The value of myArg is:” and return it. Otherwise we just return the string “test”.
Register the Field
And now we can register the field using the $field_config we have defined:
Here we use the register_graphql_field() function. It accepts 3 arguments:
The first argument is the Type in the Schema to add a field to. In this case, we want to add a field to the RootQuery Type.
The second argument is the name of the field we are registering. This should be unique on the Type, meaning the Type should not already have a field of this name.
The third argument is the $field_config, which we just reviewed.
The field in action
We can query this like so:
query {
  myNewField
}
and the results will be:
{
  "data": {
    "myNewField": "test"
  }
}
Now, we can pass a value to the argument like so:
query {
  myNewField( myArg: "something" )
}
and the results will be:
{
  "data": {
    "myNewField": "The value of myArg is: something"
  }
}
Yesterday I had the pleasure of pair-programming with Daniel Olson of Shifter and we walked through the process of registering a custom connection in the WPGraphQL Schema, and writing the resolvers for it.
You can watch the recording of the pair programming session below:
Zac Gordon put together a group of engineers to work on a formal project, GatsbyWPThemes.com to port popular WordPress themes to Gatsby themes.
Recently, Muhammad Muhsin published a tutorial showcasing how users can create a Gatsby theme using WordPress as the CMS and WPGraphQL as the API for Gatsby to consume data from.
You’re here because you’d like to learn how to create static HTML exports for your Next.js site which uses GraphQL as a data source to create dynamic pages from page components. And that site may even use WPGraphQL to pull content from WordPress.
Fantastic, this article will describe the simple process of doing exactly that.
Generally speaking, all else being equal, serving a static HTML file as a webpage is generally going to be the fastest way to get that page in your users hands. There are exceptions to every rule, but this is a pretty safe bet. This speed is great for SEO, UX, conversion rates, blah blah blah, but building a site that delivers that fast is also just fun!
Bare with me for a few moments as we setup the solution with a bit of boilerplate.
As you will see if you peruse the interactive Next.js docs, they have a simple method of enabling static HTML exports. Create a file in your project at the root directory called next.config.js, and add the following code:
What we are doing here on the lines starting with '/p…' is passing query data to the component at '/post'.
Ok, now the problem becomes clear: we need a data source to populate the query (or params, title, date, etc.) that our components rely on. But the next export doesn’t “hook into” the GraphQL data source you have likely already setup in your _app.js.
So does this mean you need to rewire everything to hook up GraphQL, write fetching logic, looping, etc?
No, it means I had to. You can just install the NPM package I created and do some basic configuration. 🙂
Ok, end of boilerplate setup. Let’s get down creating your Next.js+GraphQL+WPGraphQL+static-HTML-exported site.
By the way, you do not need to include WPGraphQL in your project to make use of this method. Though if your site has a WordPress backend, you probably should.
There are no assumptions in the code for the NPM package which rely on WPGraphQL, other than possibly the schema.
Here is the relevant bit of the WPGraphQL schema in a query result:
{
"data": {
"posts": {
"pageInfo": {
"endCursor": "PQOXYXljb25uZWN0oT6uOjEwMzg5Mg==",
"hasNextPage": true
},
"nodes": [
{
"id": "cG3zdDozMDO3MTA=",
"uri": "why-you-should-use-wpgraphql",
"title": "Why You Should Use WPGraphQL"
}
]
}
}
}
Notice the nesting of pageInfo, endCursor and hasNext page, along with nodes. It’s worth taking a quick look at the results you get from queries on your project if you are not using WPGraphQL. If your GraphQL server does not return data in this format, no problem, you can still easily use this package. You’ll just need to write a custom query result parsing function. Details below.
We’ll assume for the moment that your GraphQL server does have the same schema as WPGraphQL and move on.
First install ‘next-graphql-static-export’:
npm i next-graphql-static-export
Now create a new config-exports.js file in the root directory of your project, where we will configure the parameters that we pass to the processContent made available via the next-graphql-static-export library. The following is an example of sensible defaults:
// Include our queries. See https://docs.wpgraphql.com/getting-started/posts for basic queries
const postsQuery = require("./queries/posts-query");
const pagesQuery = require("./queries/pages-query");
const productsQuery = require("./queries/products-query");
// Your graphql endpoint
const endpoint = `https://www.website.com/graphql`;
// The custom information we pass to properly fetch data for each 'post type' or content type, the result of which is the object that Next.js needs to produce an accurate static HTML export of our site
const typeParams = [
{
pageComponent: "page",
contentType: "pages",
query: pagesQuery,
urlBase: "pages",
perPage: 100,
endpoint
},
{
pageComponent: "product",
contentType: "products",
query: productsQuery,
urlBase: "products",
perPage: 100,
endpoint
},
{
pageComponent: "article",
contentType: "posts",
query: postsQuery,
urlBase: "articles",
perPage: 100,
endpoint
}
];
module.exports = {
typeParams
};
Open up your package.json again, and add change the line pertaining to the dev script to the following:
This EXPORT env var will allow us to continue to use npm run dev to develop our site, yet avoid doing a full static HTML export every time we change a line of code (see next step for where we use this env var).
Open up your next.config.js again, and make it look similar to the following:
const processContent = require("next-graphql-static-export");
const { typeParams } = require("./config-export");
module.exports = {
exportPathMap: async () => {
if (EXPORT === "false") return {}; // This is where we use the env var we just added to the dev script.
const [pages, products] = await processContent(typeParams);
// Create the static pages with Next
return {
"/": { page: "/" }
// ...pages,
// ...products
// ...posts
};
}
};
Now go ahead and run the following again:
npm run build
npm run export
cd out
serve -p 8080
Open up localhost:8080 and you should see your beautiful site with all dynamic page fully rendered and served as static HTML!
Passing your own query result parsing function
If your schema differs from the one shown above, then you will need to pass your own query result parsing function to your typeParams in your config-export.js file. Here is an example function which exactly reproduces the existing functionality:
Note that the function takes in the queryResponse, and the current contentType, both of which are used to destructure the query result and return the following required values: nodes, hasNextPage, endCursor.
You can use any amount of logic in this function, but those values are required.
To use this function in your implementation, simply add the function as a parameter to the relevant content types. So our new config-exports.js would look like this:
// Include our queries. See https://docs.wpgraphql.com/getting-started/posts for basic queries
const postsQuery = require("./queries/posts-query");
const pagesQuery = require("./queries/pages-query");
const productsQuery = require("./queries/products-query");
// Your graphql endpoint
const endpoint = `https://www.website.com/graphql`;
// Custom query result parsing function
const parseQueryResults = (queryResponse, contentType) => {
  const {
    [contentType]: {
      nodes,
      pageInfo: { hasNextPage, endCursor }
    }
  } = queryResponse;
  return { nodes, hasNextPage, endCursor };
};
// The custom information we pass to properly fetch data for each 'post type' or content type, the result of which is the object that Next.js needs to produce an accurate static HTML export of our site
const typeParams = [
{
pageComponent: "page",
contentType: "pages",
query: pagesQuery,
urlBase: "pages",
perPage: 100,
endpoint,
parseQueryResults // Passing our function as a parameter
},
{
pageComponent: "product",
contentType: "products",
query: productsQuery,
urlBase: "products",
perPage: 100,
endpoint,
parseQueryResults
},
{
pageComponent: "article",
contentType: "posts",
query: postsQuery,
urlBase: "articles",
perPage: 100,
endpoint,
parseQueryResults
}
];
module.exports = {
typeParams
};
And that’s all there is to adapting this module to a different schema than the one natively expected. Feel free to reach out with any questions.
This snippet hooks into the do_graphql_request action, which is fired when a GraphQL request is about to be executed, and fires the function force_graphql_api_authentication
The action passes 4 args to the force_graphql_api_authentication callback: $query,$operation,$variablesand $params. For this particular case, we only care about the first argument, $query, which is the query string to be executed.
Determine if the request is an HTTP Request
Since WPGraphQL can be used internally within your Plugin and Theme PHP code to hydrate data for page templates, shortcodes, etc, locking down all GraphQL requests could have unintentional consequences, so we don’t want to prevent all unauthenticated requests from executing with GraphQL, we just want to prevent unauthenticated requests coming over HTTP.
This checks to see if the request is indeed a GraphQL HTTP Request. If it’s not, it simply returns and we let GraphQL carry on as usual. That means internal GraphQL requests using the graphql() function can be processed as usual.
Ignore Introspection Queries
GraphQL has an awesome feature where the Schema itself is queryable. Tools such as WPGraphiQL, GraphQL Playground and Altair make use of the IntrospectionQuery to fetch the Schema and render Schema documentation for users.
Then, we compare the incoming query, which is passed through the do_graphql_request action to check if the incoming query is an IntrospectionQuery or not:
And last, if we’ve determined that the incoming query is indeed an IntrospectionQuery, we return and allow GraphQL to execute as normal. This will allow GraphQL to execute the Introspection Query and send the Schema back to the tool requesting it.
if ( $is_introspection_query ) {
  return;
}
Throw an error if the request is not authenticated
Lastly, we check to see if the request is authenticated by checking for the ID of the current user. If the ID is “0”, then the request is not authenticated, so we want to throw an error.
if ( ! get_current_user_id() ) {
	throw new \GraphQL\Error\UserError( __( 'You do not have permission to access the API', 'your-textdomain' ) );
}
Conclusion
With this snippet, you can lock down your WPGraphQL endpoint so nothing will be executed if the request is not authenticated.
If you need to make authenticated requests, we recommend using WPGraphQL JWT Authentication, but any of the Auth plugins that work for the REST API plugin _should_ work well with WPGraphQL as well.
If you keep up with tech trends, you likely already know that GraphQL is one of the newer breakout technologies that people are gushing about. It’s an open source specification created and used by Facebook’s Engineering team that can be used to push and pull data between APIs and apps. REST APIs have traditionally been used for that purpose, but GraphQL has several advantages over them that you can read more about here.
If you work on the WordPress platform, you’ll be happy to learn that a GraphQL implementation exists for WordPress – the WPGraphQL plugin! The project was started by Jason Bahl and is being actively being developed by him and a number of other contributors. In this post, I’ll walk you through building a sample app that uses React and Apollo Client in the browser to fetch data from a WordPress site that’s running WPGraphQL. Let’s roll! ????????
Building Our App
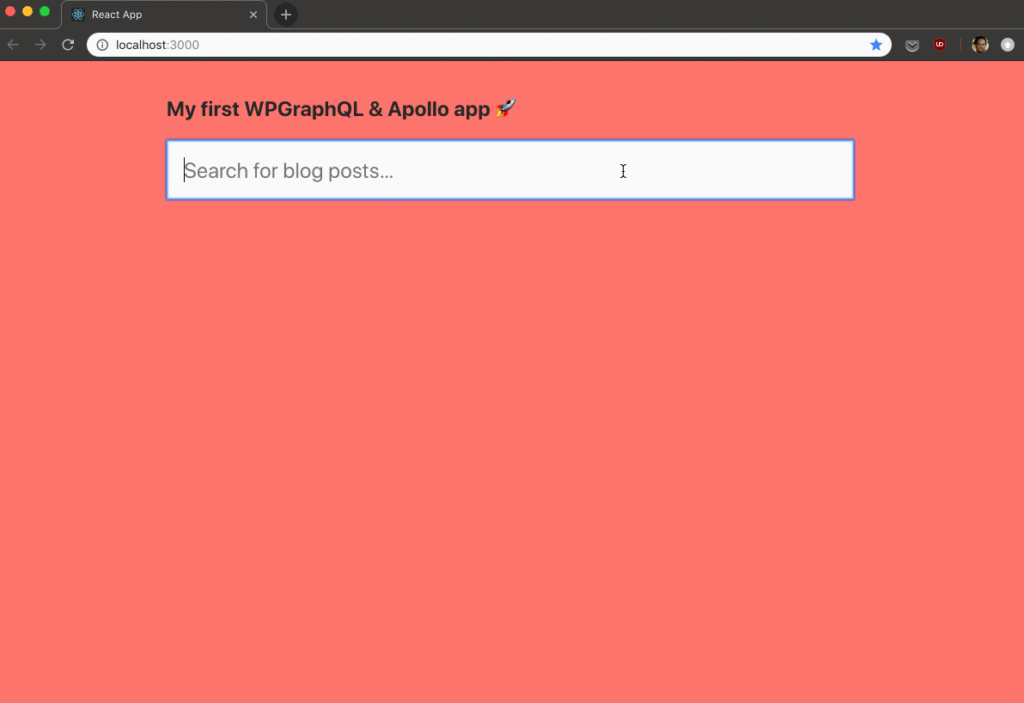
We’re going to build an app that allows you to search for blog posts. If any matches are found on the server, WPGraphQL will send back the data we requested for each post and our React app will render cards to the page for the matching posts. Here it is in action:
In order to use GraphQL, you need software running on the server to receive requests, process them then send back a response. Server implementations exist in most popular server-side languages (PHP/Node/Python/etc.). We’ll be using the WPGraphQL plugin on the server, which takes two existing PHP libraries for GraphQL (graphql-php & graphql-relay-php), and layers WordPress-specific functionality on top of them, so that it’s possible to run queries for blog posts, pages, taxonomies, settings, users, and many other WordPress-y things (these are referred to as “types” in GraphQL parlance).
Once the server supports GraphQL, you’ll also need a client-side library to help out with sending the requests to the server and receiving the responses that come back. Many such libraries exist. For our client-side app, we’ll be using Apollo Client.
Steps to Follow
1. Make sure you have node and npm installed and are mildly familiar with React and running commands on the command line.
2. Install and activate the WPGraphQL plugin on the WP site you’d like to pull data from. You should then be able to visit the /graphql endpont in a browser, such as example.com/graphql and see JSON output rather than your site’s 404 page. Don’t worry if you see a “Syntax Error GraphQL” message in the JSON output. That’s expected, since we haven’t sent a valid request to the /graphql endpont yet – merely visited it directly in a browser.
One important distinction to note here: with REST APIs, many different endpoints are used, depending on the type of data you need to send/receive. With GraphQL though, all requests use a single endpoint. The WPGraphQL plugin registers the /graphql route for that purpose.
3. Run these commands to get a fresh app up and running locally using Create React App: npx create-react-app using-react-apollo cd using-react-apollo npm start
You can now open http://localhost:3000/ to see your app. You can hit ctrl+c whenever you need to stop it, then npm start whenever you need to get it running again.
4. Install the npm packages we need. npm install apollo-boost react-apollo graphql graphql-tag
Here’s a brief description of each:
apollo-boost: Package containing everything we need to set up Apollo Client
react-apollo: Apollo Client view layer integration for React
graphql: Library for parsing GraphQL queries
graphql-tag: Library that takes ES6 template literal strings and compiles them into GraphQL ASTs (Abstract Syntax Trees) that can then be passed into Apollo Client
5. Open the project in a code editor. In the /src/ folder of your project, delete all the files except index.js and index.css to clean things up a bit.
6. Replace the contents of /src/index.js with the code below, but swap out “https://content.wpgraphql.com/graphql” with the URL of the WP site you want to pull data from.
import React from 'react';

// Helper function for formatting dates.
const formatDate = date => new Date( date ).toDateString();

const PostCard = ({post}) => {
  const { postId, title, date, author, featuredImage } = post;
  const { name: authorName } = author;

  return (

    { featuredImage && // If a featured image exists, display it.

    }
      {title}

        Date: {formatDate(date)}


        Author: {authorName}


  );
};

export default PostCard;
You can see that we’re creating a new client using Apollo and providing it with the URL endpoint to use for GraphQL requests. We’re also wrapping our entire app in a new ApolloProvider and passing to it the client we created as the client prop. The result of this is that we’ll now be able to use the react-apollo library to make GraphQL requests anywhere inside of our app.
7. Replace the contents of /src/index.css with this code to give our app some style. ????
8. You may have noticed that /src/index.js tries to import a PostsSearch component that doesn’t exist yet. Let’s fix that! Create a new /src/PostsSearch.js file and paste in this code:
This component provides the input in which users can type the text they’d like to search for. Once the search field is populated with text, it renders the PostsList component (which we’ll create next), providing the search query to it as a prop.
9. Create a new /src/PostsList.js file and paste in this code:
import React from 'react';

// Helper function for formatting dates.
const formatDate = date => new Date( date ).toDateString();

const PostCard = ({post}) => {
  const { postId, title, date, author, featuredImage } = post;
  const { name: authorName } = author;

  return (

    { featuredImage && // If a featured image exists, display it.

    }
      {title}

        Date: {formatDate(date)}


        Author: {authorName}


  );
};

export default PostCard;
This is where the magic happens ✨. At the top, we’re defining a POSTS_SEARCH_QUERY GraphQL query. It takes in a search string as an argument and tells WPGraphQL to search for WordPress blog posts that match it, and send back their data. Notice that unlike a REST API where you have no control over which data is sent back in the response, here we are telling WPGraphQL exactly what data we’d like to get back, and the shape to put it in.
In GraphQL, “edges” represent connections between nodes, and “node” is a generic term for an object – in our case those objects will be blog posts.
You can also see that we’re using the Query component and passing to it our query as well as the search string to use as the argument it gets. Query handles all the heavy lifting and provides a render prop. We are immediately destructuring the three props we receive into loading, error, and data variables. After that we have some declarative JSX code to handle all possible scenarios. Different things are rendered depending on whether:
the query is currently in progress (loading)
an error has occurred
matching posts were NOT found, or
matching posts WERE found
If matching posts were found, we map over them and render out a PostCard component for each (which we’ll create next).
10. And now for our final PostCard component that will handle rendering each individual post card. Create a new /src/PostCard.js file and paste in this code:
import React from 'react';

// Helper function for formatting dates.
const formatDate = date => new Date( date ).toDateString();

const PostCard = ({post}) => {
  const { postId, title, date, author, featuredImage } = post;
  const { name: authorName } = author;

  return (

    { featuredImage && // If a featured image exists, display it.

    }
      {title}

        Date: {formatDate(date)}


        Author: {authorName}


  );
};

export default PostCard;
That’s it! Once those four JS files and one CSS file are in place, you should be able to run npm start (if the app’s not already running), then visit http://localhost:3000/ and try searching for some blog posts. Any string you type will be used to search both blog post titles and their content, and the matching results will pop into view.
Let’s contrast our app from one using a traditional REST API for a minute – If you were to build an app like this using a REST API, you’d potentially have to make multiple requests back to the server to get all the data you need. The first REST endpoint may take in a search string as an argument and respond with a list of the post IDs for the matching search results. You’d then have to take those post IDs and make another request back to the server to get all of the data you need for those posts (title, date, author, featured image, etc.). Extra, synchronous round trips like that back to the server can be expensive and slow down your frontend app. By contrast, with GraphQL, everything can be fetched in one request. For example, you could build a complex query for getting the most recent 10 posts, then for each of the authors of those, get some of their user data (name, email, etc.) as well as a list of their 3 most recent posts in a particular category. If you’re using GraphQL, all of that data could be fetched from the server in a single request and returned to your frontend app all at once, formatted in exactly the way you requested.
This example app merely scratches the surface of what can be done with these technologies. You can dig into the documentation for WPGraphQL to learn more about working with mutations (changing or deleting data), implementing authentication, defining your own GraphQL types, connections and resolvers, and much more.
Apollo Client also has lots more to offer from sending requests for mutations to the server (in addition to query requests, like the one we send in this example app), caching query data locally, providing you with a global app data store using Apollo Link State, pagination, and many other features.
Now go forth and see what other cool things you can build with these technologies. ????
Recently, a WPGraphQL user asked how to query only sticky posts with a GraphQL query.
One of the great things about WPGraphQL is how customizable it is with hooks and filters, making it easy to extend the API for your needs.
End goal
One (of many possible) solutions would be to allow the client to specify that they only want sticky posts as an argument on the posts connection query.
A query could look something like the following:
query GET_STICKY_POSTS {
  posts( where: {onlySticky: true }) {
    nodes {
      id
      title
      date
      link
    }
  }
}
This query would allow the client to specify that they want posts, but onlySticky posts.
This should give us what we were looking for, a way to query only sticky posts using WPGraphQL.
The issue is that the onlySticky argument doesn’t exist in the WPGraphQL plugin, so if we want to use it, we’ll need to add it ourselves.
Register the “onlySticky” argument
To add this field as an argument, we can use the following snippet:
add_action( 'graphql_register_types', function() {
    register_graphql_field( 'RootQueryToPostConnectionWhereArgs', 'onlySticky', [
        'type' => 'Boolean',
        'description' => __( 'Whether to only include sticky posts', 'your-textdomain' ),
    ] );
} );
Here we hook into the graphql_register_types action, to make sure the GraphQL Type registry is ready to be hooked into.
Next, we register a field to the GraphQL schema by using the register_graphql_field() method.
The first argument is the name of the Type to register the field to. In our case, that Type is RootQueryToPostConnectionWhereArgs. This is the Input Type that is used by the root posts field to provide filters to the query.
The next argument is the name of the field we’re registering. Here, we’re using onlySticky as the field name.
The third argument is an array to configure the field. We declare the Type the field should be is Boolean, meaning it should be either true or false, and provide a description for the field.
At this point, our query would validate, as onlySticky would be a valid argument on the query now, but our actual results aren’t affected.
Filter the WP_Query to respect the onlySticky input
The next step we need to take is to filter how WPGraphQL resolves the query and make sure it respects the onlySticky argument that was input.
Here, we filter graphql_post_object_connection_query_args. This filter can be found in the PostObjectConnectionResolver.php file in the WPGraphQL plugin.
This allows for the $query_args that are prepared to send to WP_Query for execution to be filtered prior to WP_Query fetching the posts.
Inside this filter, we check to see if the $args that were passed through the resolver from GraphQL include the onlySticky input, and if that value is true.
If those conditions are met, then we define custom $query_args, by first getting a list of the sticky posts, then asking to query only those IDs and the posts_per_page equal to the number of sticky posts we have.
Then we return the modified $query_args for WP_Query to use to resolve the query.
In action
Now, we can see our query in action.
First, go set a couple posts to sticky, if you haven’t already:
Screenshot showing a few sticky posts
Then, using WPGraphiQL, execute the query, and the results returned should only be the Sticky posts!
GIF showing how the query with onlySticky set to true, and the results being only sticky posts
Conclusion
My hope is that this shows how easy it is to extend WPGraphQL for your system’s needs. The plugin is powerful out of the box, but if you have custom needs for your application, take advantage of the various hooks and filters in the plugin to make it work for you!